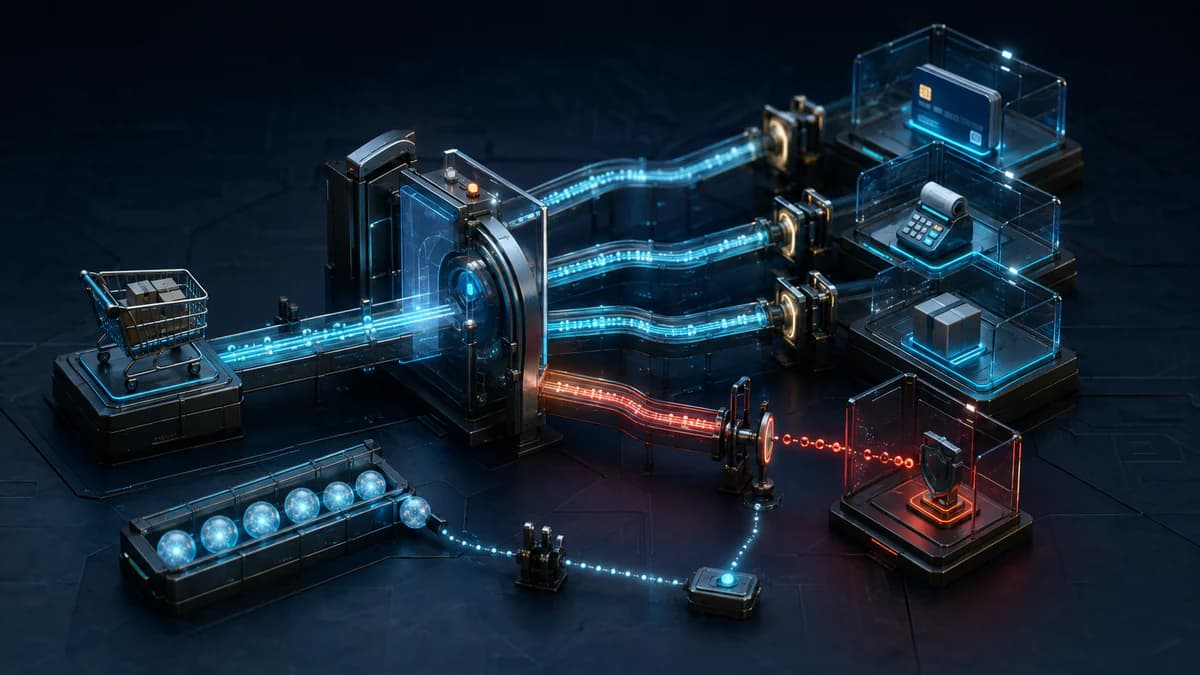
A local fault must not become a checkout outage
A purchase crosses more systems than the interface reveals: cart, promotions, tax, fraud, payment, inventory and delivery promise. When one dependency slows down, the problem is not just a late response. Waiting work retains connections, threads, memory and pool capacity; new requests queue up until a healthy service degrades beside the failed one. A contained provider incident can then become a cascading checkout failure.
A circuit breaker contains that effect. It does not repair the remote provider; it protects the caller by stopping calls when success is unlikely. Useful ecommerce design therefore starts with business capabilities rather than a client library. Payment authorization, duty calculation, fraud assessment and delivery estimates carry different risks and permit different fallbacks.
Map dependencies and semantics before thresholds
For every checkout step, record its owner, criticality, failure modes, idempotency and permitted degraded behavior. A compact capability matrix distinguishes mandatory decisions from deferrable enrichment. If a gateway has not authorized a payment, an order cannot be described as paid. If recommendations fail, checkout can continue without them. If a precise delivery estimate is unavailable, a conservative window may be acceptable when the customer is told clearly.
Draw the correctness boundary
A fallback is not any convenient answer. It must preserve domain invariants. Reusing cached tax may be valid only for an eligible territory, product and validity period. Silently approving a missing fraud decision is not equivalent. Product, operations, security and compliance should approve the rule and encode it in the service contract. Otherwise, a breaker merely replaces a visible interruption with incorrect commercial data.
Build one end-to-end deadline
A call timeout is not the total time available to checkout. Browser, edge, application, orchestrators and providers all spend portions of one deadline. If each layer starts a fresh, full timeout, a late retry can continue after the shopper has already left. The remaining deadline should be propagated, and components should reject work that can no longer deliver a useful result.
Concrete values depend on observed percentiles, network margin, capability importance and the experience budget; there is no universal setting. As an illustrative model only, a team may reserve portions for application work, the dependency and a fallback. The testable rule is that queuing, processing and every allowed attempt must fit within the journey’s boundary.
Expose connection, queue and read time
One opaque timeout hides where time is spent. Observe pool wait, connection setup, negotiation, remote processing and response reading separately. The limit must cover the whole operation as implemented by the platform, without leaving an unprotected phase. Pools remain finite, so this design belongs beside disciplined ecommerce connection-pool sizing.
Treat the circuit breaker as a state machine
In the closed state, calls pass and outcomes populate a health window. When the policy sees material degradation, the circuit opens and returns a controlled failure or fallback immediately, conserving remote and local resources. After a recovery interval, it becomes half-open and admits a limited set of probes. Healthy probes allow gradual closure; failed probes reopen it.
The breaker key should match the real failure unit. One global breaker can disable healthy providers, while one per shopper may collect too little evidence. Boundaries commonly follow provider, endpoint, region or operation. Error classification matters too: a legitimate card decline is not an availability failure, whereas timeouts, network errors and server failures may inform operational health.
Prevent flapping and recovery surges
A window that is too short reacts to noise; one that is too long protects too late. Recovery should not release all traffic simultaneously toward a provider that has just returned. Limited probes, progressive admission and jitter spread demand. Thresholds must be calibrated from production evidence and controlled tests, never copied mechanically from another system.
Cap retries with a shared budget
Retries can recover transient failures, but they also multiply load. When every layer repeats, a small local policy becomes many calls against an already distressed dependency. Choose one layer to own retries, require idempotent operations or idempotency keys, and enforce a budget. A retry budget defines the additional demand allowed relative to original traffic and runs out as health worsens.
Attempts need increasing backoff with jitter so clients do not return in synchronized waves. Do not start another attempt when the remaining deadline is insufficient or the breaker is open. Permanent errors, business declines and unsafe operations should not be retried automatically. Retrying is a selective decision, not the default response to every exception.
Isolate resources with bulkheads and pressure control
A breaker limits future calls, but in-flight work and queues may already occupy capacity. Bulkheads separate pools, queues, workers or processes so one slow provider cannot consume every checkout resource. Payment and shipping quotation can have distinct concurrency budgets; saturation in the second capability should not stop healthy work in the first.
Queues must be bounded and paired with early rejection. Accepting unlimited work turns memory into a hidden queue and stretches latency toward collapse. Rate limits and backpressure complete the design: ecommerce API rate limiting controls incoming demand, while bulkheads and breakers govern how admitted traffic uses outbound dependencies.
Observe decisions, not just errors
A useful dashboard separates latency, timeouts, saturation, rejections, additional attempts and outcomes by dependency and operation. It shows breaker state, transition reason, fallback volume, retry-budget consumption and probe health. Global checkout averages can remain calm while one region or endpoint is failing.
Traces and logs should connect the original deadline to child calls without recording sensitive data. An operation identifier reveals whether several attempts belong to one purchase. Distributed tracing for ecommerce checkout separates queue, processing and network time. Alerts should describe capability impact, such as checkouts without a delivery estimate or payments suspended, rather than only technical error counts.
Test degradation and govern release
Resilience behavior must be tested by introducing latency, errors, broken connections and reduced capacity in a controlled environment. Verify that deadlines hold, retry demand stays bounded, the breaker opens and recovers without a surge, bulkheads preserve healthy functions and the shopper sees a truthful message. Test recovery too, because caches and queues may contain delayed work when service returns.
A release checklist assigns owners to thresholds and fallbacks, links runbooks and dashboards, documents the operational switch and defines when a capability should be disabled. Every numeric setting is an engineering hypothesis to validate, not a universal constant. To apply the model to a real storefront, map dependencies, invariants and capacity with our ecommerce systems services. Success is not a world without failures; it is a failure that remains contained, observable and recoverable.
Frequently asked questions
What is the difference between a circuit breaker and a retry?
A retry repeats a request when recovery is reasonably likely; a circuit breaker temporarily stops calls when signals show that persistence would amplify the failure. They are complementary controls, not substitutes.
Should every checkout dependency use the same timeout?
No. A timeout follows from the end-to-end budget, the capability’s criticality and the dependency’s measured behavior. Payment, tax, fraud and shipping can require different semantics and fallbacks.
When is it safe to degrade an ecommerce capability?
Only when the fallback preserves correctness, transparency and risk constraints. A delivery estimate may be deferred; a payment authorization or regulatory check must never be fabricated.
How should teams verify the behavior before production?
Run controlled tests that introduce latency, errors and reduced capacity, then observe deadlines, breaker transitions, queues, pools, fallbacks and recovery. Release criteria should cover degraded operation as well as the happy path.
Related articles
Ecommerce database connection pooling: sizing, timeouts and capacity
A practical method for allocating connection budgets, controlling queues and preventing checkout peaks from turning the pool into a failure multiplier.
Ecommerce API rate limiting: protect login and checkout without blocking customers
An operational model for applying different limits to login, catalogue, cart, checkout and integrations, with actionable 429 responses and false-positive metrics.
Ecommerce distributed tracing: diagnose checkout and orders with OpenTelemetry
An operational method for tracing checkout and orders, propagating context, correlating providers, protecting data and sampling without losing incidents.